n8n is a workflow automation tool that combines business-process automation with AI capabilities. A workflow connects a starting event to a sequence of steps: receive data, transform it, call another service, check the result, and decide what should happen next. The official documentation describes n8n as fair-code licensed and provides both cloud and self-hosted setup paths.
For a beginner, the most useful mental model is not “an AI that runs the business.” It is a visible flow of small operations. Each operation has an input and an output. You can inspect the data at every step, run tests manually, and keep a person responsible for decisions that carry editorial, financial, privacy, or operational risk.
This guide explains that model, then walks through a three-node workflow that validates a fictional content idea without calling an AI service. You will check a successful result, reject a missing audience and restore the valid input. The later sections show how that small boundary can grow into an AI-assisted workflow with human review.
The four parts of an n8n workflow
An n8n workflow is made from nodes and the connections between them. The official guide to working with nodes explains that trigger nodes start workflows in response to events or conditions. Other nodes perform actions or transform the data that moves through the workflow.
The four concepts to understand first are:
- Trigger: the event that starts a workflow. A trigger might be a manual click, a schedule, a webhook, or an event from another service.
- Node: one step in the process. A node can set values, run code, transform data, or call an external service.
- Connection: the path that passes output from one node to the next.
- Execution: one run of the workflow, including the data and result produced by each step.
Start with a Manual Trigger while learning. According to the official Manual Trigger documentation, this node starts the workflow when you select Execute Workflow. It is designed for workflows that you want to run only when you choose, which makes it a good fit for controlled prototypes.
Run a three-node workflow before adding AI
Start with the free Topic Intake Validator. It turns a fictional content idea into a predictable JSON item and stops when required information is missing. The download contains three connected nodes: a Manual Trigger labelled When clicking 'Execute workflow', Sample Topic Input and Validate and Normalise Input. It does not generate an article or call an AI service.
You need an existing n8n workspace where you can import and run a test workflow. No OpenAI credential is needed for this example. The workflow download is free; using your n8n instance remains subject to its plan and execution limits.
Import the existing example
- Open the Topic Intake Validator page and select Download workflow JSON.
- In a new n8n workflow, open the top-right menu and choose Import from File. Select n8n-topic-intake-validator.json.
- Inspect the canvas before running it. You should see those three nodes, with no model, HTTP Request, email or publishing node. The trigger type is Manual Trigger; its imported label is When clicking 'Execute workflow'.
- Open Sample Topic Input, an Edit Fields (Set) node. Keep the four required fields as String values and enter the fictional values below.
- topic: How to prepare a weekly editorial checklist
- audience: Small agency content teams
- search_intent: learn
- content_pillar: n8n Workflows
- primary_cta: Explore the workflow library
The first four fields are required. primary_cta is optional. Use fictional values even in a manual test: n8n can retain execution data according to its workflow settings. This example has no separate storage node, but that does not disable your instance's execution history.
Check success then failure
Select Execute Workflow and inspect the JSON output of Validate and Normalise Input. The item should preserve the sample values and add status with the value validated and workflow_stage with the value topic_intake. The validator trims surrounding spaces and lowercases search_intent. For example, a String value of Learn surrounded by spaces becomes learn.
Now clear only the audience value and run the workflow again. Expect the validation node to stop with Missing required fields: audience. Restore Small agency content teams and rerun the workflow; the validated result should return. This success, rejection and recovery sequence gives you a small boundary you can inspect before adding another service.
The required fields must be non-empty strings. A numeric value such as 42 is rejected with Invalid field types (expected string): audience when it reaches the validator as a number. The text 42 is still a string. When testing types, inspect the upstream JSON type rather than judging by the characters shown in the editor.
A validated result means that the input has the required shape. It does not establish search demand, factual accuracy or editorial approval. For the complete field contract and further negative cases, continue with validating content ideas before using AI.
Import menu labels can vary by n8n version. The official import and export guide documents the JSON import route. Keep this exercise manual and review the file again before adapting it.
How data moves between nodes
Each node receives items, works with their JSON or binary data, and returns items to the next connected node. A content workflow might start with a topic, audience, search intent, and content pillar. A validation step checks that the required values are present. An AI step produces a structured brief. A later step turns the approved brief into a draft.
n8n expressions let a field use data from earlier in the execution. The current expression reference documents built-in variables for items, nodes, execution context, dates, and other workflow data. Expressions are useful, but they are not a substitute for validation. If a required field can be empty or malformed, check it explicitly before sending it to another service.
A predictable workflow therefore has two layers:
- Transformation: convert incoming values into the format required by the next node.
- Validation: reject missing or unexpected values before they create a bad downstream result.
Structured AI output strengthens this pattern. Instead of accepting an arbitrary paragraph, define the fields the next step needs, such as title, slug, introduction, sections, conclusion, call to action, and complete Markdown. Validate those fields again after the model responds.
Credentials belong in the credential store
External services usually require authentication. n8n has a dedicated credential system for this purpose. Its credential documentation describes credentials as securely stored authentication information used to connect workflows to APIs and databases.
Do not place API keys in prompts, Set nodes, Code nodes, workflow names, exported JSON, screenshots, or Git commits. Select a saved credential in the node that needs it. Before sharing an exported workflow, inspect the file and remove environment-specific credential identifiers if the recipient should choose their own connection.
Apply the same discipline to test data. Use fictional or non-sensitive topics while building the flow. Limit each integration to the permissions it genuinely requires. If a secret is pasted into chat, an issue, or source control, revoke it and create a replacement.
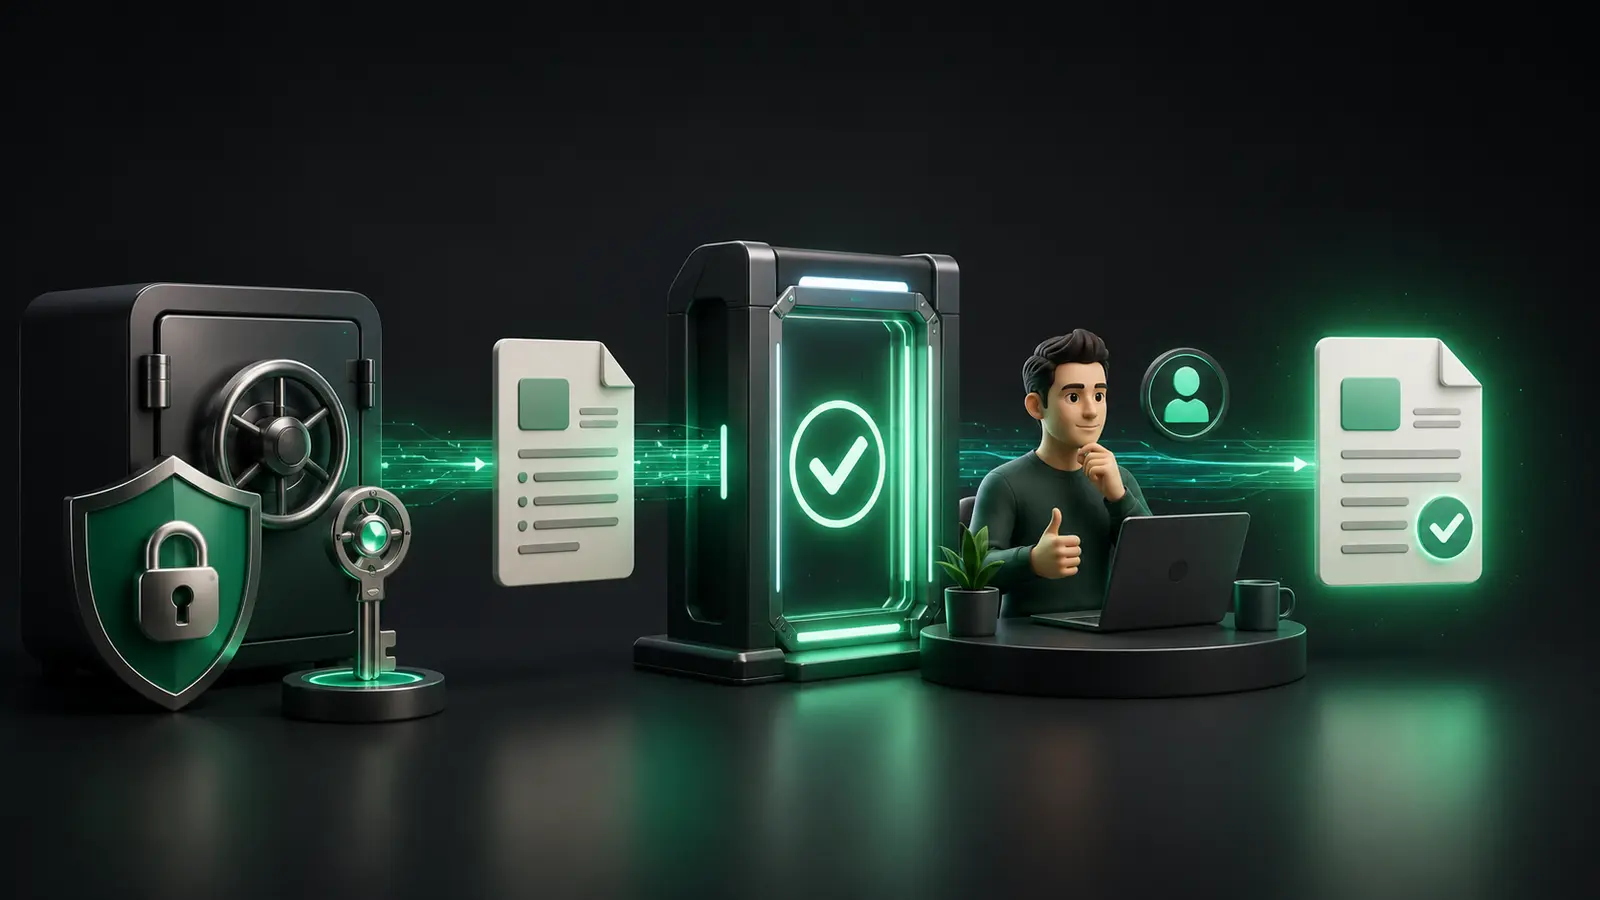
Extend the first test into an AI content workflow
Once the three-node example works, treat the following sequence as a larger design to build and test in stages. These steps are not included in the free validator download:
- Start the workflow manually.
- Enter a topic, audience, search intent, and content pillar.
- Validate every required field.
- Generate a structured editorial brief.
- Require a person to approve or reject the brief.
- Generate a structured article draft only after approval.
- Run a quality gate over the draft.
- Require a second human approval.
- Package the approved article as Markdown.
- Stop before storage or public publishing.
This design makes failures visible. A missing input stops before the AI request. A rejected brief stops before draft generation. A quality failure stops before packaging. A rejected draft stops before the content is considered ready.
Human review should be a real decision, not a decorative status field. The reviewer should check the argument, tone, factual claims, links, privacy, possible secrets, and whether the call to action matches the reader’s needs. n8n also documents human-fallback patterns for AI workflows, which are useful when an automated response is uncertain or cannot safely complete the task.
What the quality gate should check
A basic draft quality gate can be deterministic. It does not need another model call to confirm obvious requirements.
Check at least:
- all required fields exist and contain values;
- the article has the expected minimum number of sections;
- the full Markdown passes a sensible minimum length;
- the meta description stays within the project’s chosen limit;
- the slug uses a stable lowercase, hyphenated format;
- second-level headings are not duplicated;
- the content does not match known API-key or bearer-token patterns;
- statements requiring editorial verification remain visible to the reviewer.
These checks do not prove that an article is accurate. They prove that it is structurally complete enough for human review. Accuracy still requires appropriate sources and editorial judgment.
Test both success and failure
A successful execution is only half of a workflow test. Deliberately trigger each important guardrail.
For input validation, empty one required field and confirm that execution stops with the field name. For human review, set the decision to rejected and confirm that downstream nodes do not run. For the quality gate, temporarily remove a required draft field or shorten the article and confirm that packaging is blocked.
After every negative test, restore the original value and execute the affected step again. Leave the workflow in the safe state: approval logic restored, production trigger disconnected, and publishing inactive.
Also inspect unexpected conditions:
- unusually long input;
- an AI response that is not valid JSON;
- a response missing one required property;
- an external API timeout or quota error;
- a repeated execution that could create duplicate content;
- content containing a value that resembles a secret.
Record the observed result rather than assuming the error path works.
From prototype to production
Do not add scheduling, notifications, a database, and automatic publishing all at once. Introduce one boundary at a time.
First, keep approved Markdown in version control so changes are reviewable and reversible. Next, add a storage layer only when its content model, permissions, backups, and failure handling are defined. Add notifications after the approval responsibility and destination are clear. Consider a production trigger only after repeated manual runs are reliable.
When the workflow becomes production-facing, document ownership, retry behavior, timeouts, duplicate protection, error alerts, credential rotation, and the rollback path. Review the data-handling terms, permissions, limits, and costs of every external provider before increasing volume.
Build the starter workflow
Open the free Topic Intake Validator, download the JSON and complete the success, rejection and recovery checks above. Keep the sample manual and use fictional data.
When that boundary is clear, follow Build Your First AI Content Workflow in n8n to add a reviewable brief. The AI stage needs a separately configured provider credential and may incur model usage charges. Keep automatic publishing disconnected and obtain human approval before delivery.
Use the current official documentation while building:
- n8n documentation hub
- Build your first workflow
- Work with nodes
- Manual Trigger node
- Create and edit credentials
- Expression reference
- Set a human fallback for AI workflows
Interface labels and integration options can change. Treat the documentation for your current n8n version and chosen provider as the source of truth.